7. Running a whole cohort
Background. A real study has tens to hundreds of subjects. Running them is a scheduling question, not a scientific one: the backend and run policy change speed and failure handling, never the habitat labels.
Purpose. Run the same study on the serial and process backends and
check the labels match; see what happens when one subject fails
(on_subject_failure), resume from checkpoints, set a per-subject
timeout, cap workers to the GPUs, and learn when parallel is actually
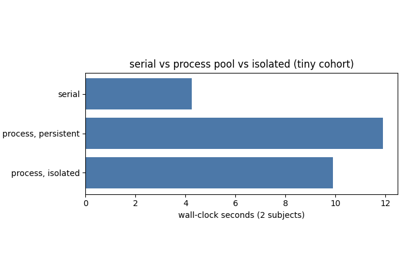
worth it (on a tiny cohort serial can be faster because Windows spawn
start-up dominates).
Running the same study on each backend